Articles
Writing on building with AI
Private AI Research: What 8 Experiments Showed
Two months of hands-on experiments on the real cost of running your own AI, from a laptop GPU to Google Cloud. The takeaways, the numbers, and when private AI actually makes sense.
Why We Didn't Upgrade to the Bigger GPU
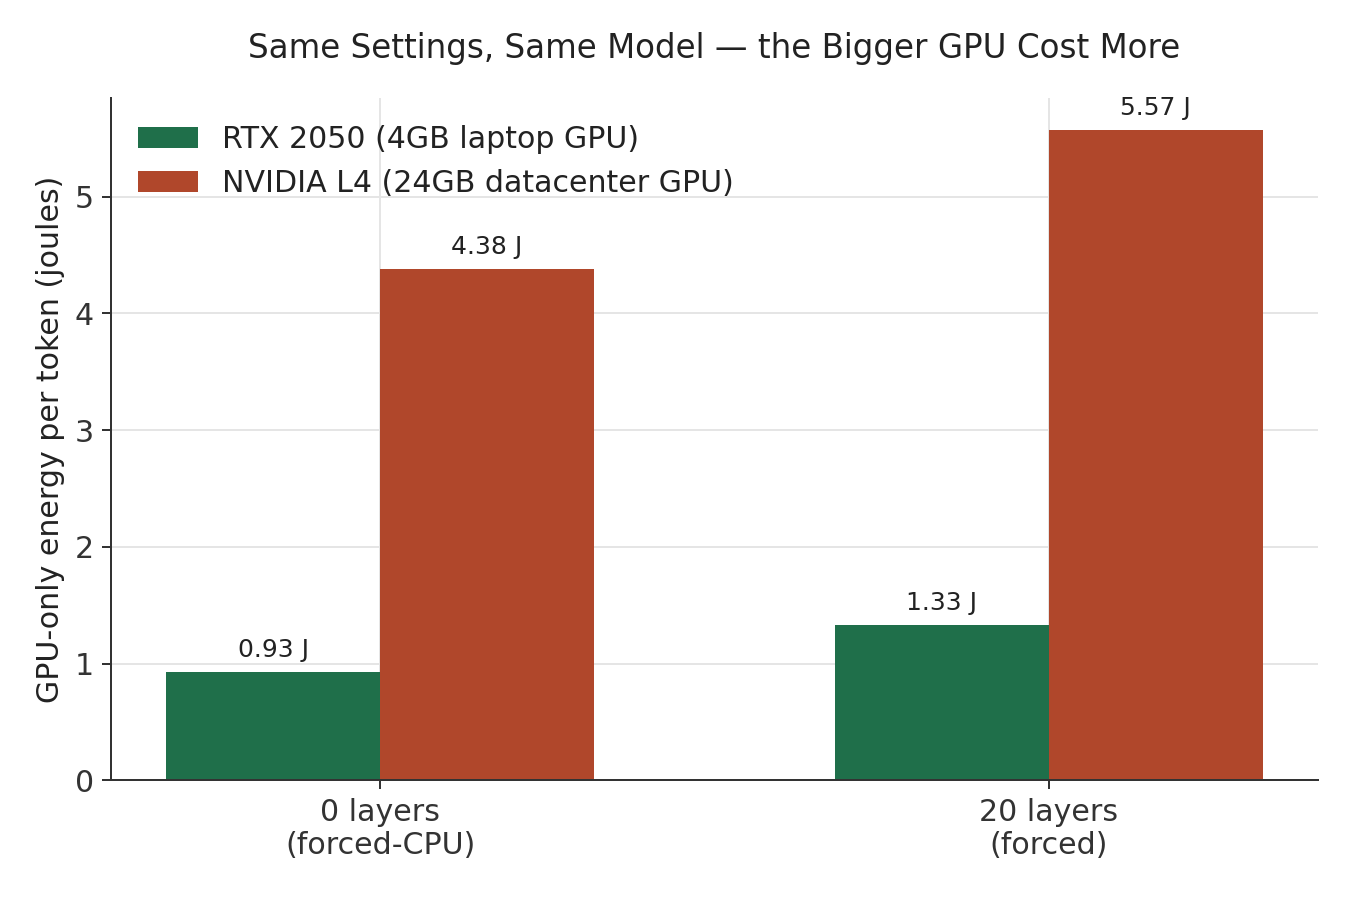
A 24GB datacenter GPU running the same model, the same settings, was 4-5x less energy-efficient per token than a 4GB laptop card. Here's what that means for hardware selection.
Where Does Your Prompt Actually Go? API vs. Private Cloud vs. On-Prem, Compared
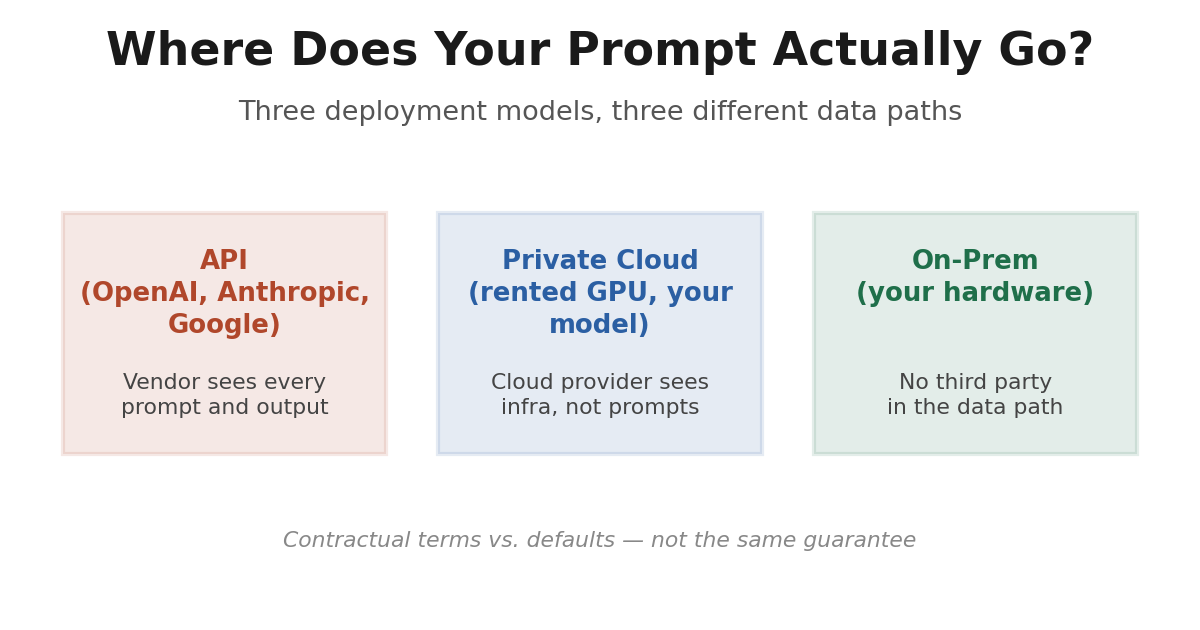
What OpenAI, Anthropic, and Google's current API terms actually promise about your data — and how that compares to running the model yourself, on rented or owned hardware.
We Ran the Same Benchmark Twice and Got a Different Answer
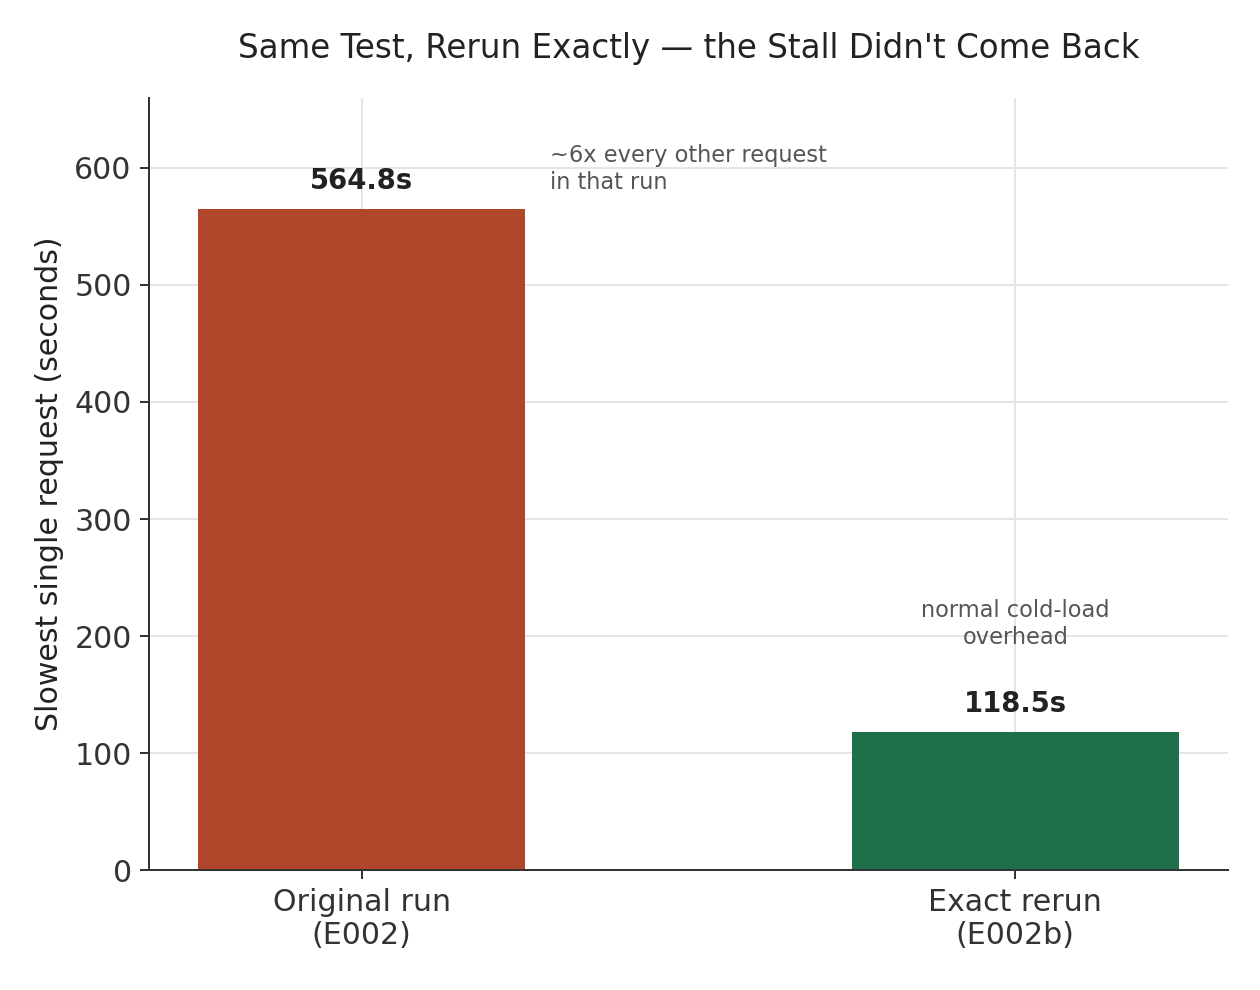
One run of an LLM inference benchmark showed an 8.3x slowdown. The exact same test, rerun unmodified, showed 5-6x — and the dramatic result didn't happen at all the second time.
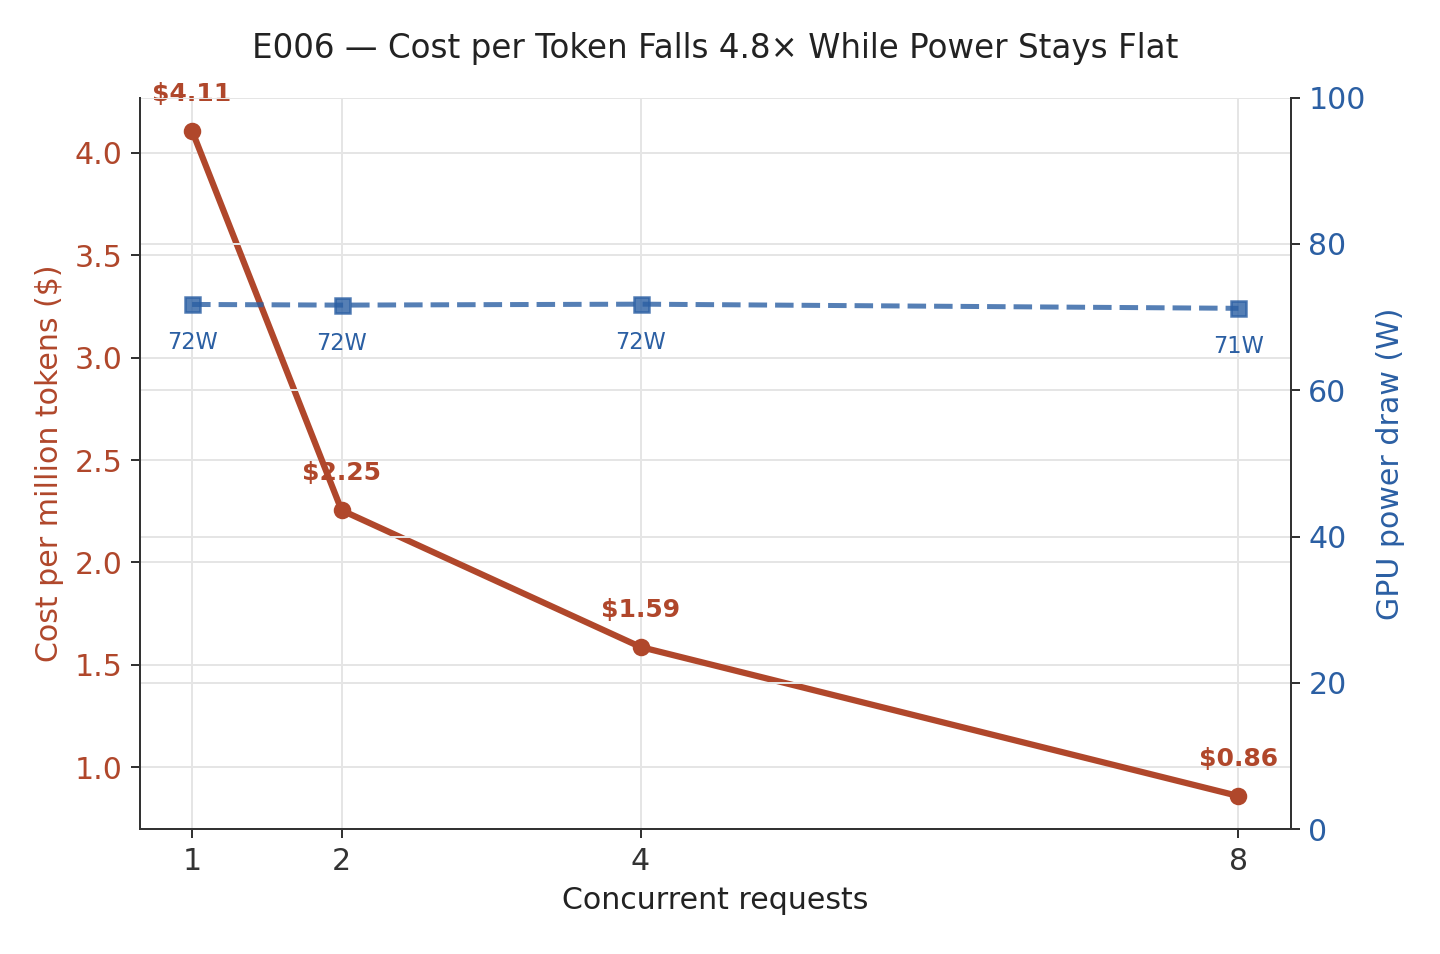
One Config Change Cut Our Inference Cost 4.8×
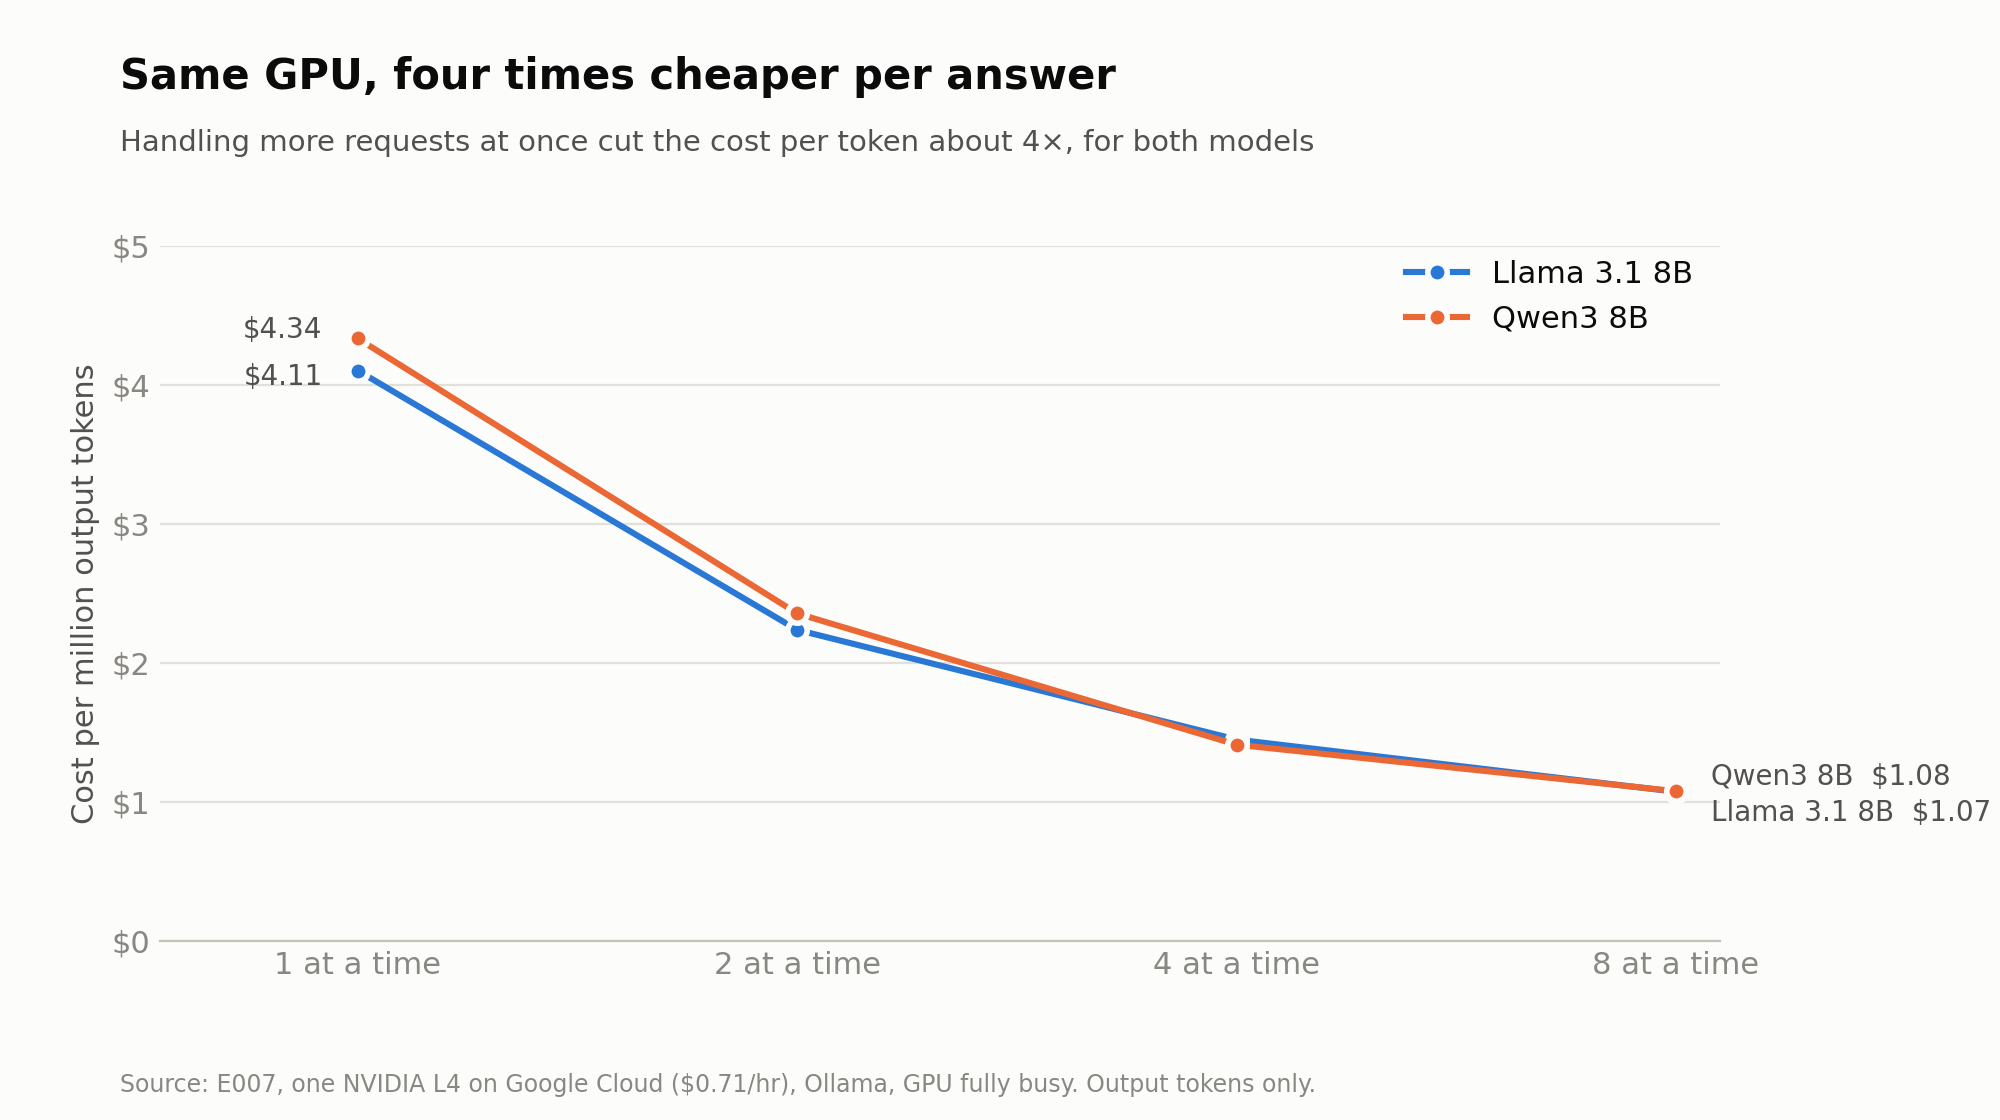
We assumed our GPU was nearly maxed out at 96% utilization. Raising concurrency from 1 to 8 requests cut cost per token 4.8× anyway — with power draw barely moving.
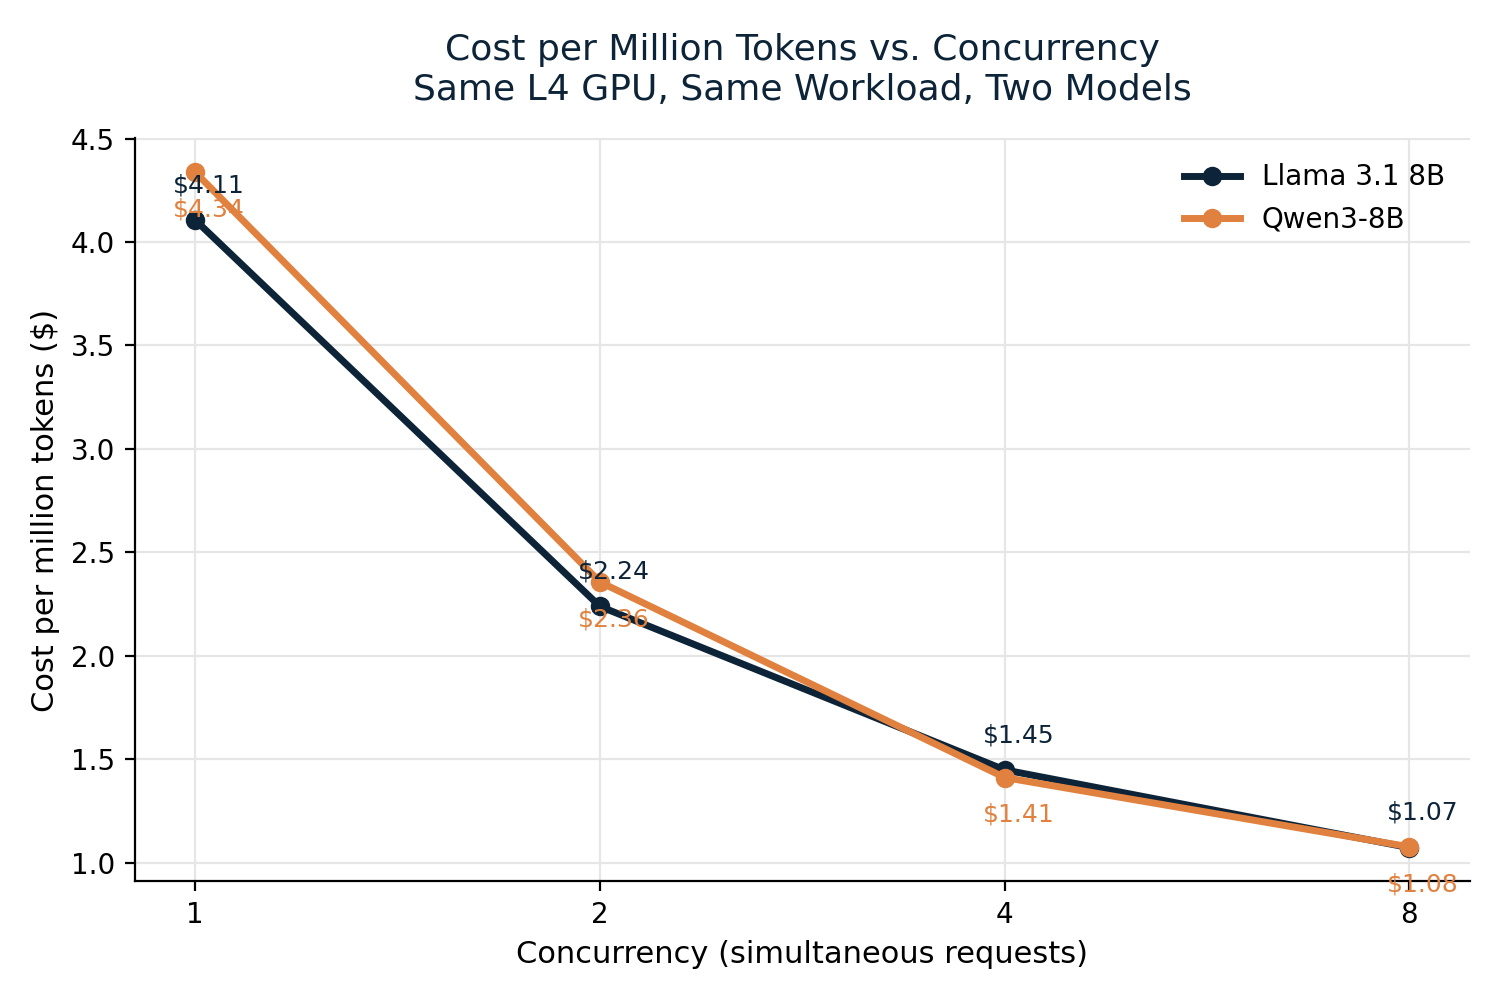
We Tested Our Concurrency Finding on a Second Model — It Held
Llama 3.1 8B and Qwen3-8B show the same concurrency-vs-cost curve on the same GPU — and what that does and doesn't tell you about sizing private LLM infrastructure.
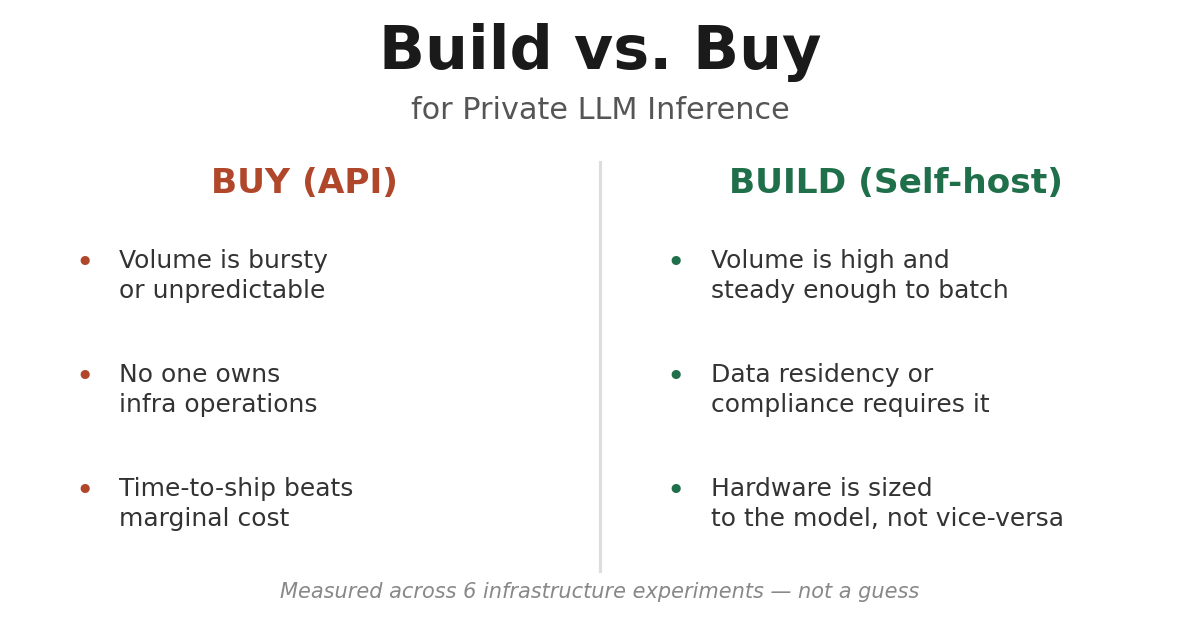
Build vs. Buy for Private LLM Inference: What the Numbers and the Operations Actually Cost
Real cost and operational data from six infrastructure experiments — what self-hosting an LLM actually takes, versus what it looks like on a spec sheet.
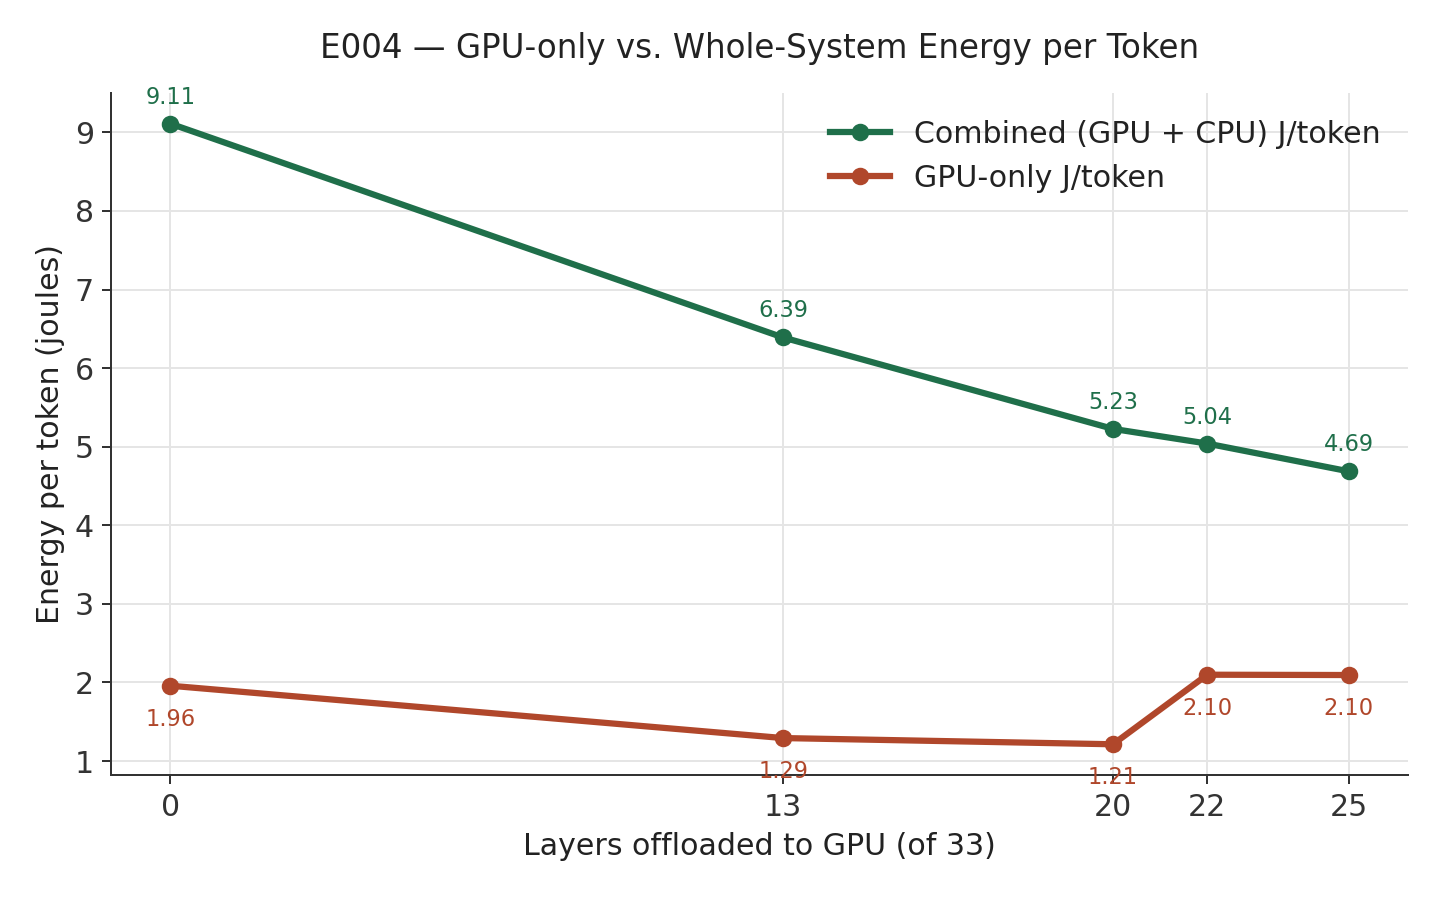
The Metric That Kept Lying to Us: Six Experiments in Private LLM Infrastructure
Six experiments in private LLM inference — and four times the obvious metric pointed to the wrong decision.
Claude Skills for UI/UX: How to Build a Website That Doesn't Look Like AI Slop
Testing a Claude UI skill against a dedicated UX and accessibility audit — where visual polish ends and interaction correctness begins.